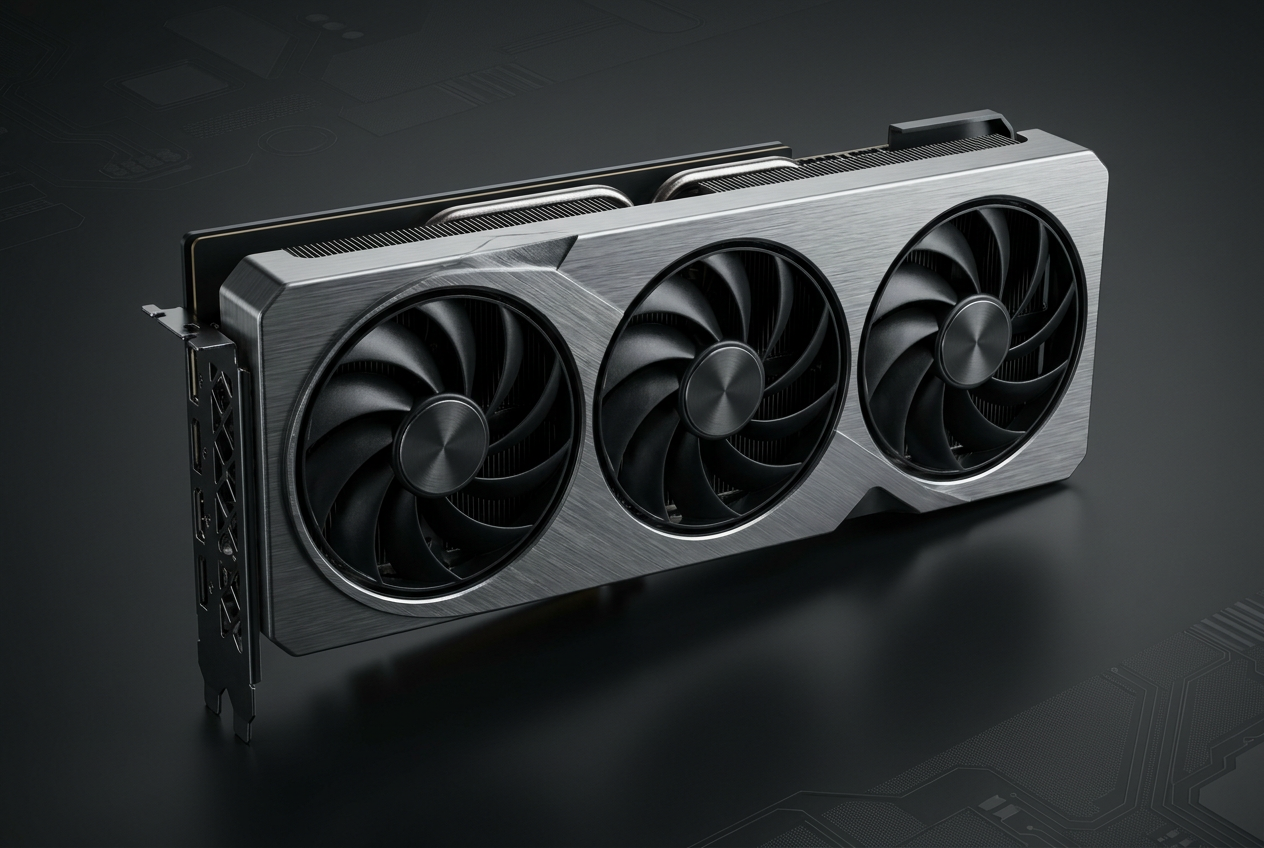
You've probably experienced this: you're deep into a game or rendering something demanding, and suddenly the screen freezes, but the sound keeps playing. It's a frustrating situation where it seems like your PC has crashed, but what's actually happened is that the graphics card driver has failed , and the system is trying, sometimes unsuccessfully, to restart the device.
Understanding how the recovery process works for an AMD GPU is vital to avoid having to force a shutdown every time there's an error. Depending on whether you're using Windows, a Linux distribution, or advanced computing environments with ROCm, the solutions range from a simple keyboard shortcut to complex hardware isolation configurations on servers.
GPU reset in Windows: Quick solutions
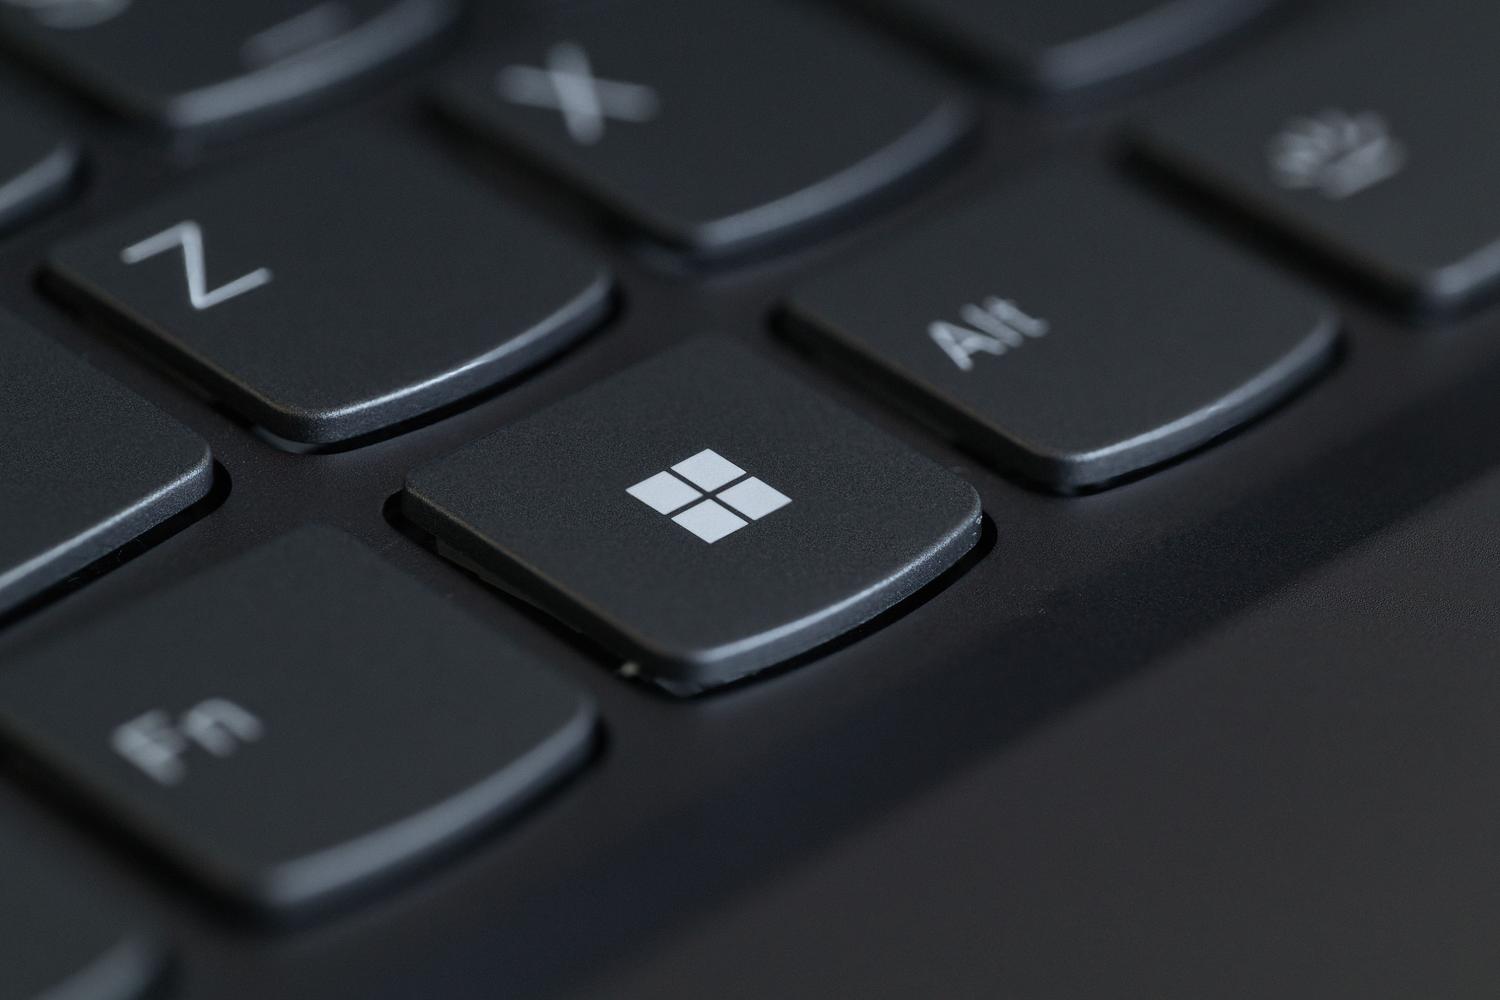
In modern systems running Windows 10 and 11, there's a feature called TDR (Timeout Detection and Recovery) that attempts to automatically restart the driver when it detects that it's unresponsive. However, when this fails, we have a very useful secret shortcut which is pressing simultaneously Win + Ctrl + Shift + BWhen you do this, the screen will flicker briefly while the system refreshes the graphics driver.
If the keyboard is unresponsive or the problem persists, another option is to open Device Manager, find the Display adapters section, right-click on the GPU, and disable the device, then re-enable it . This forces a manual driver reinstallation. In more severe cases, where the driver is corrupted, it's best to use tools like DDU (Display Driver Uninstaller) in safe mode to perform a clean install before configuring hardware components on your PC with the latest driver version from the AMD website.
Recovery in Linux and high-performance environments
In Linux, things get more technical. When a amdgpu_job_timedoutThe kernel attempts to reset the IP block. Sometimes this is successful. soft-resetwhich is ideal because it doesn't erase the VRAM, but if that fails, the system resorts to full resetThe problem is that, even if the log says the reset was successful, the desktop environment (like KDE with X11) may freeze, leaving the user without a mouse or keyboard and forcing a physical restart.
For those working with AMD Instinct and XGMI connections, the scenario is more complex. A reset on a single GPU can affect others that share the same "hive." To prevent a failure from bringing down the entire system, it is recommended Use isolation via containers, cgroups, or VM passthroughIt is not enough to use variables like ROCR_VISIBLE_DEVICES, since these are user filters and do not create a real barrier at the kernel level.
Advanced isolation and recovery strategies
To maximize server availability, the best practice is to assign a single workload per XGMI hive . If virtualization is used, PCIe passthrough via VFIO is the most robust option, as the virtual machine manages its own kernel and ROCm stack, limiting the "burst radius" of a crash. Some users, in environments like Unraid, even use scripts to decouple the PCI device via virsh before shutting down a VM, preventing the host from experiencing a kernel panic.
When a computing application undergoes a reset, it cannot simply continue running. It must close all handlers, reopen the /dev/kfd device , and reallocate memory and kernels. To speed this up, some developers implement saving the GPU state to host memory, allowing for a much faster re-initialization.
Improvements to legacy hardware (GCN)
It's not all new software; systems using older GCN architectures are also receiving improvements thanks to the Valve team. They are working on enabling soft reset support for GFX8 IP blocks (like Polaris or Fiji), which would allow only the graphics portion to be reset without losing the video memory, drastically improving the user experience on older hardware.
Having a clear action plan, from Windows keyboard shortcuts to hive segmentation on Instinct servers, helps reduce downtime. The key lies in identifying whether the failure is a temporary driver glitch or a stability issue caused by overclocking or overheating, and then applying a recovery strategy proportional to the severity of the error to maintain system stability without constantly restarting the computer.