If you're tired of monthly subscriptions draining your wallet or token limits killing your momentum just when you're at your best, you're not alone. Setting up your own local AI environment is the ultimate solution to regain control, protect your code, and stop relying on the whims of cloud servers.
For those venturing into this field, especially with powerful machines like the new Mac mini M4, the ecosystem can seem like a maze. However, the key is understanding that you don't need a single magic tool, but rather to assemble a stack composed of an inference engine, a specialized code model, and an interface that acts as an autonomous agent.
The pillars of a local code assistant
To make everything work without having to copy and paste snippets of code like crazy, you need four well-defined layers. First is the runtime or execution environment , where Ollama and LM Studio currently reign supreme due to their ease of use in serving models via OpenAI-compatible APIs. Next comes the language model (LLM) , which is the brain that reasons; here, the Qwen2.5-Coder family has become the gold standard for its balance between size and capacity.
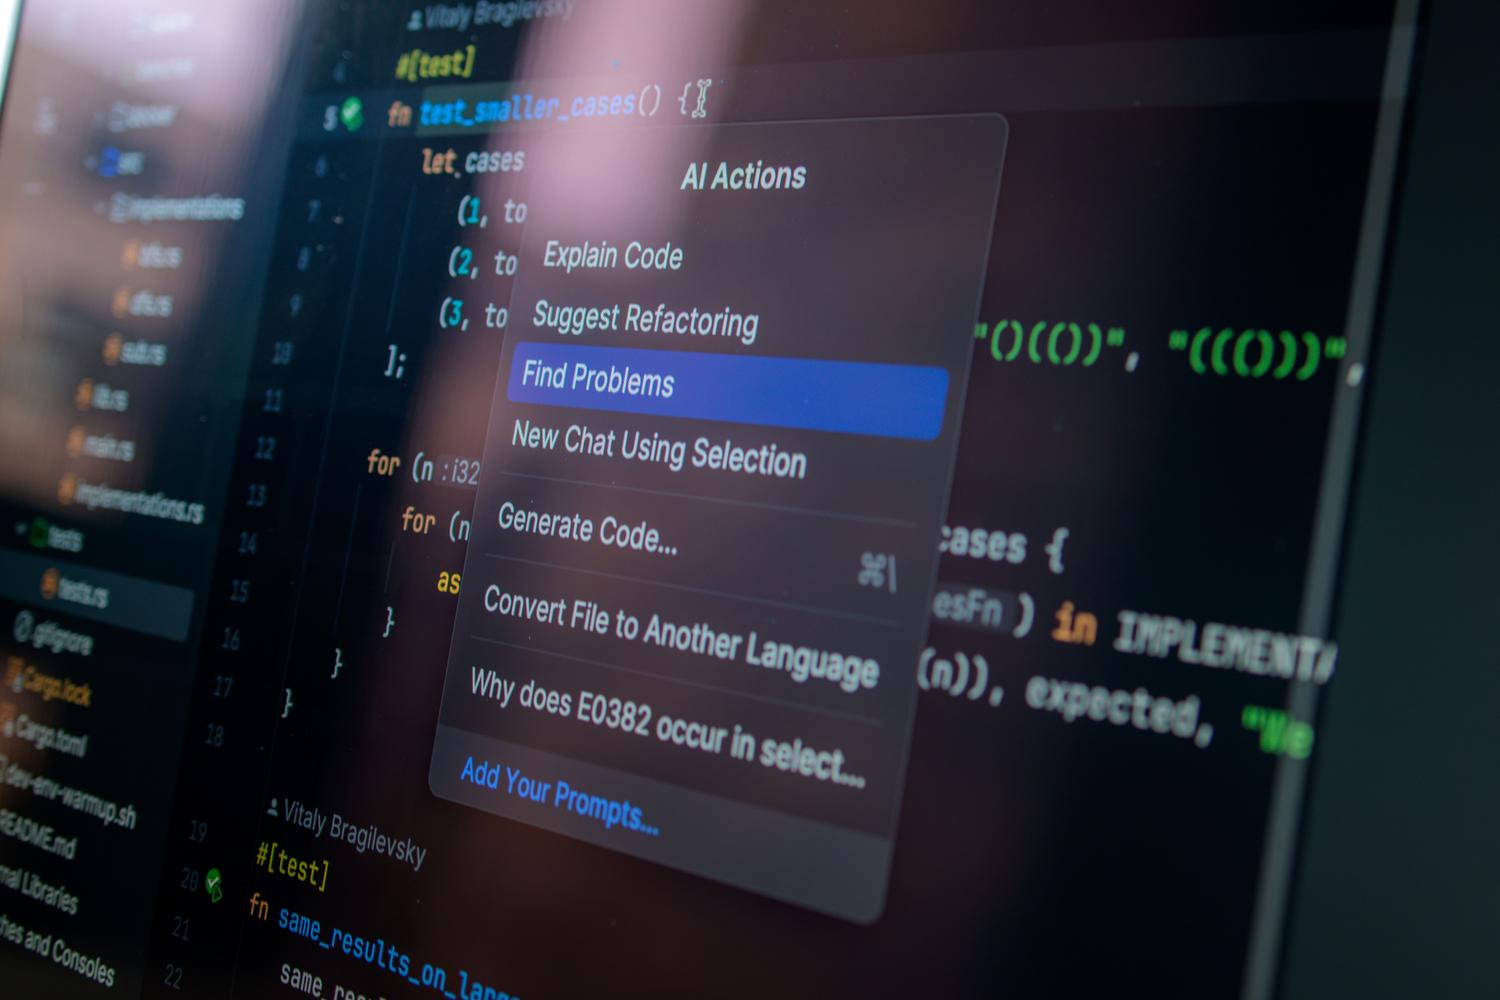
The third piece is the IDE client or interface , such as the Continue extension for VS Code, which provides autocomplete and integrated chat. Finally, there are action agents , which are more advanced tools like Cline or Aider, capable of reading entire files, executing commands in the terminal, and proposing actual changes to the repository under your supervision.
Recommended models based on your hardware
Not all models will fit every machine. The golden rule is that unified memory, or VRAM , is the real bottleneck, much more so than the raw power of the processor. If you have a basic computer with 16GB of RAM, 7GB or 8GB models are your best bet for fast tasks and light chat.
- Qwen2.5-Coder 1.5B: Ideal for instant autocomplete (tab-autocomplete) without slowing down your computer.
- Qwen2.5-Coder 7B/14B: The sweet spot for those seeking a balance between speed and logical reasoning.
- Qwen2.5-Coder 32B: For those with 24GB of VRAM or more who need a serious and professional coding that approaches the quality of commercial models.
- DeepSeek-Coder-V2 Lite: A brutal alternative for heavy logic tasks or complex algorithms.
Tools and Agents: Which to Choose?
Depending on how much autonomy you want to give the AI, you have several options. If you prefer something integrated into the editor, Continue is the perfect entry point. If you're looking for an agent that can automatically edit multiple files and manage Git commits, Aider is the ultimate terminal power tool, as it optimizes token usage through repository maps.
On the other hand, we have Goose , a highly versatile open-source agent that can interact with the file system and be extended via MCP servers. For those seeking something more visual, AnythingLLM allows for local knowledge management and document indexing, although it's more of a productivity tool than a pure developer. There are also emerging projects like OllamaCode , which focus on enabling AI not only to write code but also to execute and test it in real time.
Step-by-step setup for an efficient workflow
To get everything working perfectly, the ideal thing to do is start by installing Ollama and downloading the model that best suits your memory (for example, ollama pull qwen2.5-coder:14bOnce the model responds correctly on the console, we connect it to VS Code using the extension Continueconfiguring the localhost URL so that chat and edits take place on your own machine.
If you want to take things to the next level, you can install Cline to have an agent that suggests changes to the shell and files, always asking for your permission before executing anything. For a more robust workflow, using Aider will allow you to perform multi-file refactorings with amazing accuracy, taking advantage of the agent's understanding of your Git structure.
Privacy, costs, and performance
The major advantage of this approach is absolute privacy ; your trade secrets and API keys never travel to any external server, which is vital if you work in regulated sectors. Furthermore, once you've invested in the hardware, the cost per token is literally zero, eliminating the frustration of usage limits in cloud Pro versions.
In terms of performance, latency drops dramatically since there are no round trips across the network. However, be careful with the KV cache ; if you notice the AI suddenly slowing down, you've probably run out of VRAM and the system is using regular RAM, which is much slower. The solution is to reduce the context size or use a smaller model.
Tips for not breaking the project
Giving your terminal keys to an AI can be dangerous without oversight. The smartest approach is to apply a restrictive permissions principle : let the AI read the files first, then propose a plan, and only then write the changes. Never allow an agent to execute commands to delete files or perform bulk installations without first verifying the exact command.
It's recommended to work in dedicated Git branches for AI testing. This way, if the agent decides to refactor and breaks the entire project, you can revert to a single command. The winning approach is: small goal, context inspection, approval of a limited patch, and validation with real tests before making the final commit.
The combination of a runtime like Ollama, powerful Qwen series models, and autonomous agents like Aider or Cline transforms a personal computer into a self-contained development workstation. By prioritizing unified memory and managing execution permissions, any programmer can eliminate reliance on cloud quotas and enjoy a smooth, private, and completely free workflow.